AI research acceleration is a bottleneck question, not a staffing multiplier
METR’s Anthropic assessment invites a practical question: which constraint must move before faster tasks become faster research?
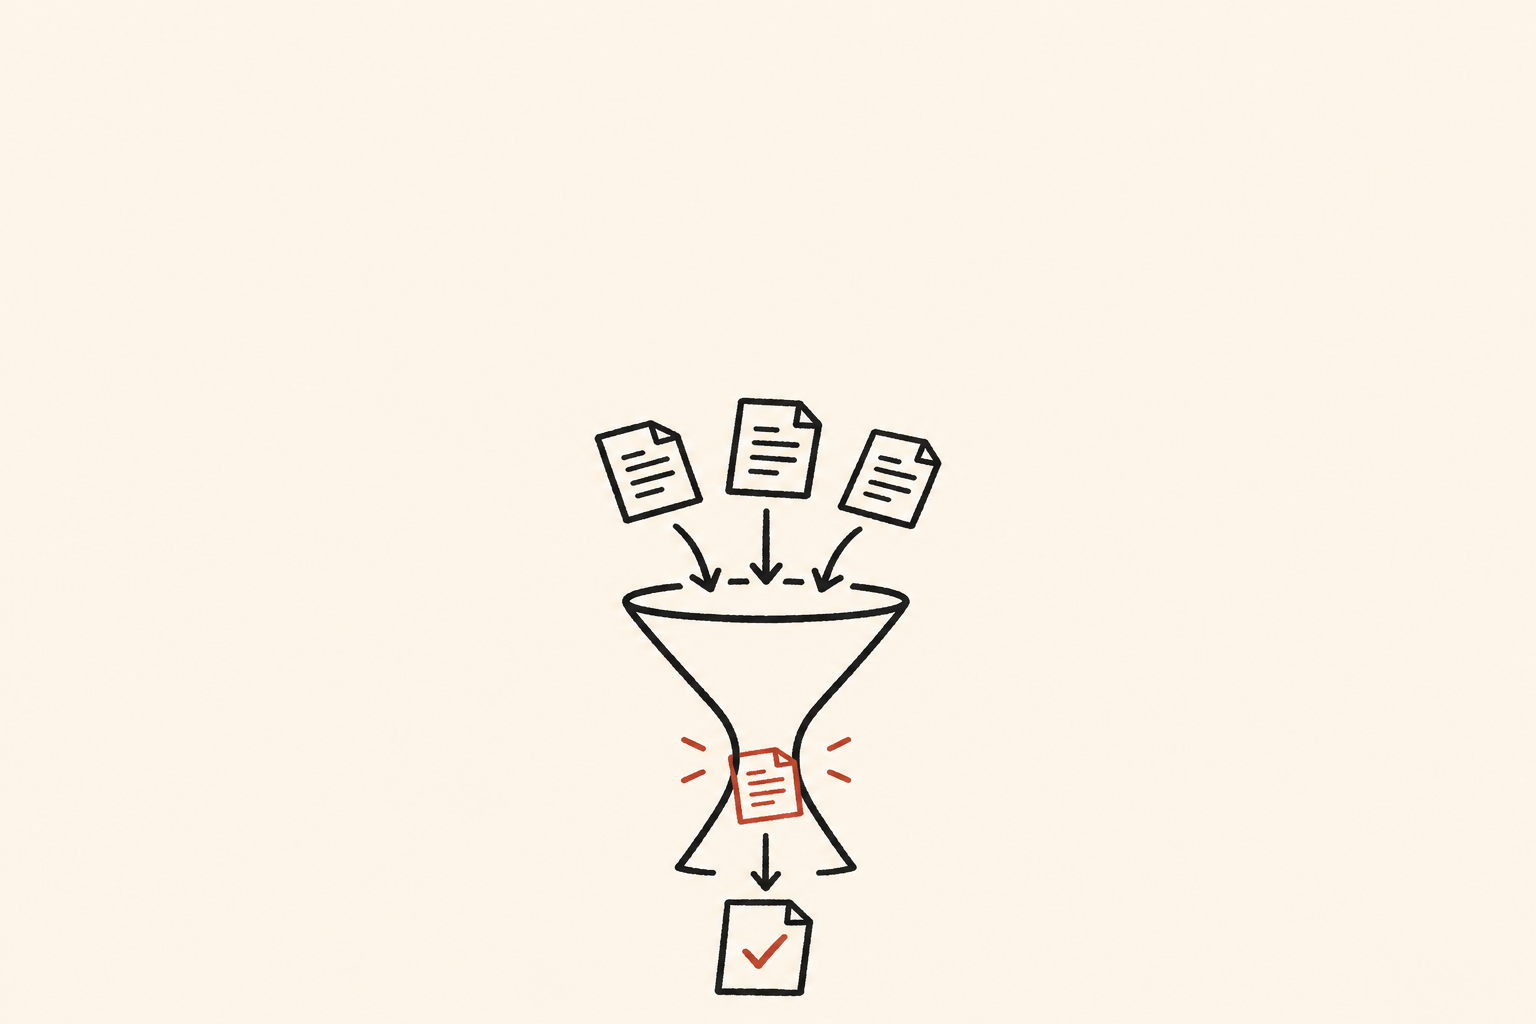
METR’s November 5 assessment of AI R&D at Anthropic is useful for planning, but not as a coefficient to paste into a staffing spreadsheet. Its findings concern one research organization. Converting them into a promise that another team can halve headcount or delivery time would require evidence about that team’s own workflow.
The distinction matters because a research program does not sell completed prompts or generated code. It needs trustworthy findings that change what happens next. The operational question is therefore not just how much faster a researcher works, but how much sooner the organization can make a better, validated decision.
Three different clocks
A task clock measures time spent implementing an experiment, cleaning data or drafting an analysis. A cycle clock runs from a testable question to an accepted result, including queues, review and reruns. A progress clock measures whether those results improve the system or answer an important question. A gain on the first clock need not translate proportionally to the other two.
METR’s October assessment proposal separates capability progress, AI attribution, future bottlenecks and methodological limitations. That separation is also a useful management discipline: “we completed more tasks” and “we learned more” should not occupy the same dashboard cell.
Consider an explicitly hypothetical, sequential ten-day experiment cycle: four days of implementation, four of waiting and execution, and two of checking results. Halving implementation takes the total to eight days. That is a 20% time reduction, or a 1.25× cycle-speed improvement, not 2×. The arithmetic is not an estimate of Anthropic. It shows why even a genuine task-level improvement cannot be applied indiscriminately to a whole program.
This example also has limits. Real teams overlap work, share infrastructure and choose experiments adaptively. Parallelism can improve utilization, while one blocking dependency can delay several projects. The useful response is to map the actual dependency chain, not to treat the illustration as a universal production formula.
The bottleneck can move
Suppose implementation really becomes faster. The team may submit more experiments to the same compute pool. If execution capacity stays fixed, waiting times can grow. Or more results may arrive at the same small group of reviewers, shifting the constraint from making artifacts to deciding which ones deserve trust.
Neither outcome means the tool failed. It means a local improvement changed where capacity is scarce. A team that measures only code volume could celebrate while its question-to-decision time barely improves. Conversely, a team could run fewer, better-designed experiments and create more value despite modest growth in activity metrics.
The November report did not identify convincing near-term bottlenecks to continued rapid progress at Anthropic, while stressing uncertainty about that judgment. This is not a finding that every organization has spare compute, data and review capacity. Nor does it mean those inputs have ceased to matter. A constraint absent at one scale or moment can become binding after the workload changes.
For a smaller laboratory, the first useful investment may be experiment scheduling, reproducible environments or a shared evaluation harness. For another it may be additional compute. These are conditional planning implications, not claims about Anthropic’s internal investment priorities.
Budget for accepted evidence
A practical pilot should record three things together: elapsed time from question to accepted result, the fraction of results that survive independent checking, and total cost per accepted result. The cost denominator should include failed runs, inference, review and rework, rather than only the price of the assistant.
“Accepted” must mean something stable. Teams should specify the evaluation protocol before comparing periods, retain negative results and log changes to task difficulty. Otherwise, a shift toward easier experiments can resemble productivity growth. A reviewer should be able to reconstruct what was tried and why the conclusion followed, not merely reproduce a polished summary.
A useful comparison keeps the question mix and quality bar reasonably similar. Where feasible, stagger access or compare matched tasks rather than relying solely on retrospective impressions. METR’s 2025 developer experiment, which found a slowdown in its particular setting, is a reminder that tool use and measured benefit are different variables. It is not a forecast for current models or a result that can be transferred unchanged to frontier research.
Metrics should also allow useful failure. Rigorously rejecting a hypothesis can prevent a large investment in the next round. Rewarding only positive outcomes may discourage the experiments most capable of challenging the central assumption. Useful research is not the same as a count of apparently successful experiments.
Buy flexibility before committing the whole plan
The planning choice is not a binary bet on acceleration or stagnation. Teams can preserve options: expand tool access in stages, reserve capacity for replication and reviews, and commit additional infrastructure when queues and validated output demonstrate the need. Staff changes are harder to reverse than pilot budgets, so task-speed evidence alone is a weak basis for them.
A good budget review asks what would change the next allocation. If coding time falls but review backlog rises, invest in evaluation capacity. If reviewers are available but execution queues dominate, investigate compute scheduling and capacity. If throughput rises without more useful decisions, revisit experiment selection. These are diagnostic branches, not a guarantee that every bottleneck can be removed cheaply.
The strongest reading of the new assessment for operators is thus a demand for more precise measurement. Faster assistance can matter a great deal. Its economic value appears when it shortens the path to reliable decisions, and the next scarce resource may be different from the last one.
Information only. No investment, legal, tax, or financial advice.