When AI compresses evidence, preserve the conditions that change the answer
Context compression needs tests for missing dependencies and conflicting evidence, not only relevance scores.
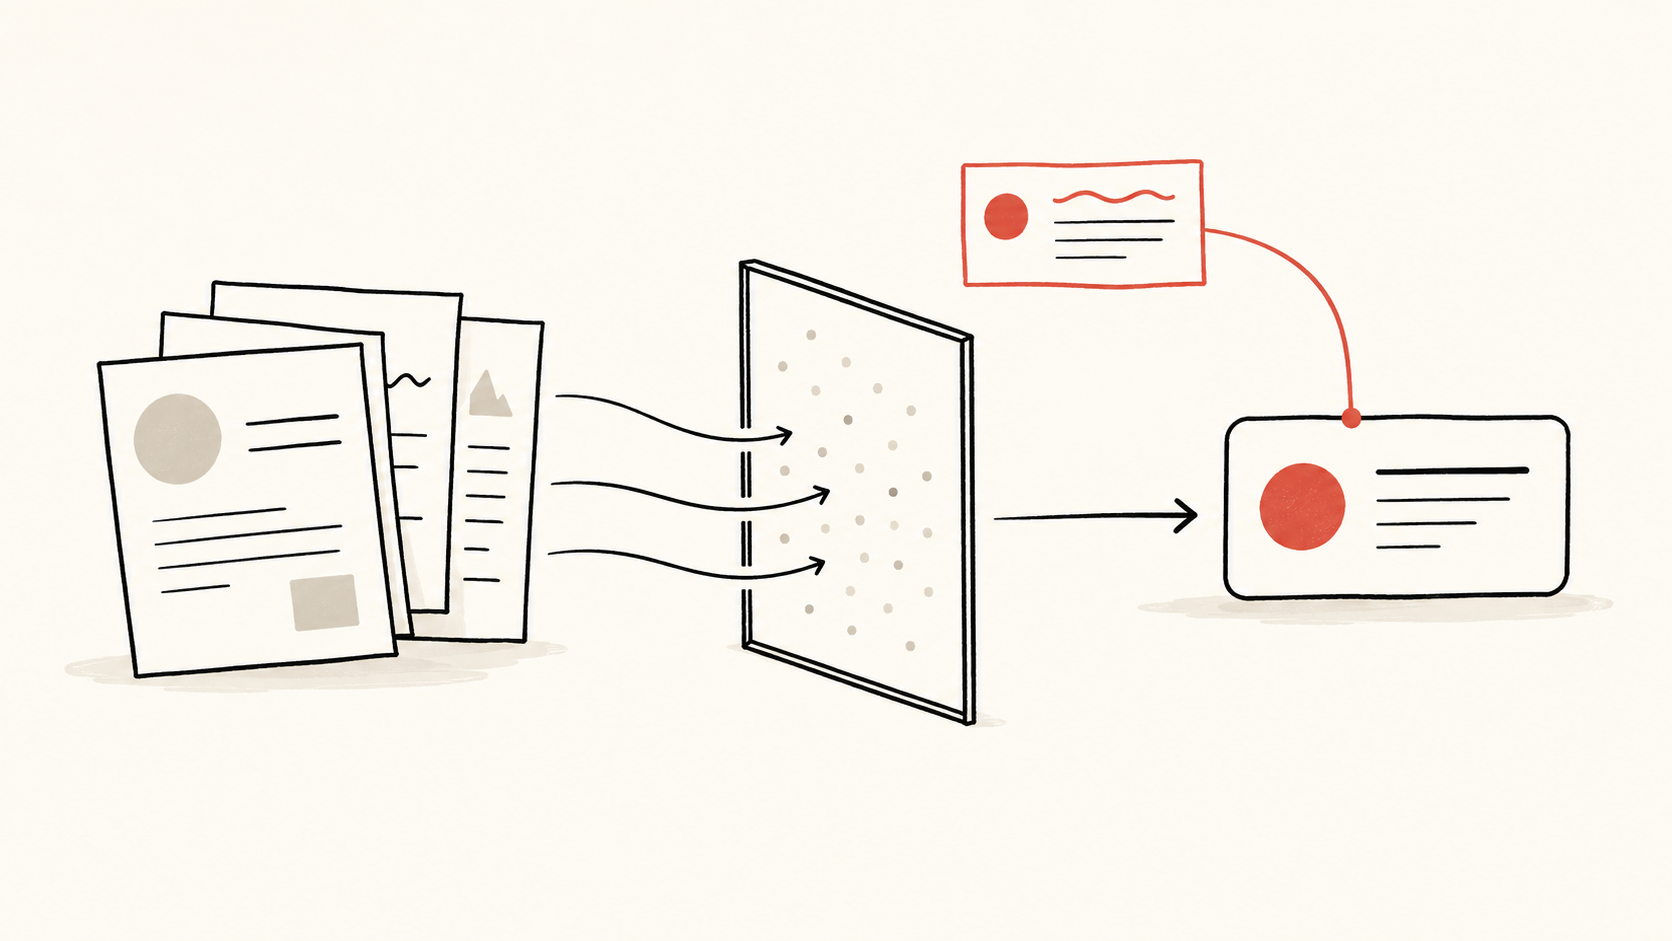
An enterprise search system can deliver a highly relevant passage while withholding the information needed to use it correctly. A sentence may answer the question in isolation, yet become inapplicable once a later amendment, a definition in another document, or an unresolved conflict is considered. As retrieval systems take on more of the work of selecting what a model sees, this distinction deserves its own engineering treatment.
The immediate occasion is Cohere’s October 21, 2026 release of Rerank 5, whose optional Context Focus returns relevant spans within documents. Our concern here is broader than this product. We have not independently tested it. The analysis below asks how a system should establish that its selected context is sufficient for a particular decision, without treating a relevance score as that guarantee.
A passage can depend on another passage
Consider a hypothetical equipment-maintenance assistant. One document describes a calibration procedure; a later bulletin limits its use to an earlier hardware revision; a parts register identifies which revision is installed. A technician asks which procedure applies. Each record serves a different role. The procedure supplies the instructions, the bulletin changes their applicability, and the register connects those conditions to the equipment in question.
Ranking the procedure first may be entirely reasonable. Returning only its most directly responsive paragraph could nevertheless leave the decision incomplete. The important unit is the relationship among the records. Individually, the hardware register may look less similar to the user’s wording than several detailed procedure documents. Its contribution appears when the system checks the condition that makes one procedure applicable.
This hypothetical example does not establish that any particular retriever fails. It shows why a retrieval objective and a decision objective can diverge. A system optimized to select passages that discuss a topic needs an additional way to notice that a conclusion depends on an unresolved condition. Increasing the number of passages may help, but it offers no assurance that the necessary relationship has been recovered.
Define what “enough evidence” means
For bounded workflows, a useful design begins with the questions that must be settled before the assistant can answer. In the example, these include equipment identity, document applicability, and whether a later instruction supersedes an earlier one. The retrieval process can then seek evidence for those dependencies rather than merely collecting more text about calibration.
This should remain proportionate. A request to locate a document title does not need the same evidentiary burden as selecting an operational procedure. If every search triggers exhaustive dependency resolution, the system can become slow and obstructive. The appropriate boundary is the consequence of the requested answer and the kinds of conditions that can plausibly change it within the defined task.
Nor can a system certify completeness against information it cannot access. An answer should distinguish “supported by the records checked” from “all relevant records have been checked.” The latter requires a credible account of the document collection, its coverage and version state. An inaccessible bulletin or an unindexed register cannot be made irrelevant by a confident generated explanation. When such a gap matters, stating the unresolved dependency is more useful than presenting a polished final instruction.
Test whether the answer changes when the evidence changes
A practical evaluation can use paired cases. Keep the user’s question and most documents unchanged, then change one verified applicability condition. In one case the procedure remains valid; in the other a revision restriction makes it unsuitable. Review whether the system retrieves the changed evidence and whether its conclusion changes for the right reason.
The cases should also include changes that ought not to matter. Reordering paragraphs, adding a relevant-sounding but non-operative note, or supplying another copy of the same procedure should not automatically reverse the answer. Otherwise a system could appear sensitive to critical conditions while actually reacting to superficial differences. Domain reviewers must define the expected outcome before judging the generated responses.
There is a useful historical warning here. Lost in the Middle, first submitted July 6, 2023, found that evidence position affected performance in its tested models and tasks. This is not a result about today’s deployment. It motivates testing the deployed system’s own ordering choices, instead of assuming that restoring longer context solves every omission.
The evaluation should preserve intermediate evidence: which documents were candidates, which spans survived, and what reached the answer model. If the critical bulletin never entered the candidate set, changing the final prompt cannot address the whole failure. If it survived selection but the model ignored it, increasing retrieval coverage alone may waste effort. Keeping these stages distinguishable makes corrective work more precise.
Conflict deserves space in the context budget
A particularly important case is disagreement between apparently applicable records. Selecting the clearest or most frequently repeated statement can conceal the conflict. Duplicate copies of an older procedure should not silently outweigh a single controlling update. Conversely, a document that merely looks newer should not automatically prevail without evidence about its scope and authority.
For consequential workflows, reserving room for unresolved conflicts and the metadata needed to interpret them is a defensible design choice. A short answer can explain which condition remains unsettled and point the reviewer to both records. That may consume more context than a streamlined passage, but it preserves the reason a final answer would be premature.
Ragas, first submitted September 26, 2023, separates retrieval, faithful use of context and answer quality as evaluation dimensions. Our further judgment is that fidelity to selected text cannot, on its own, prove that selection was sufficient. A perfectly faithful answer can inherit an upstream omission. The paired-case approach above is one way to examine that separate weakness; it is not a claim of a complete or universally validated evaluation method.
Give compression a reversible boundary
The commercial case for shorter context remains sensible when unnecessary material consumes resources or distracts from the task. The proposed safeguard is selective expansion. When a known dependency cannot be resolved, the system can retrieve the linked record, widen the passage, or route the case for review, subject to existing access controls. It should retain the identifiers needed to reconnect a passage with its source and version.
This creates a more informative deployment question than whether compression works on average: for which task classes can the system recognize when its evidence is insufficient? Teams can examine unresolved cases, unnecessary escalations and errors that passed through without warning. These outcomes expose the trade-off between efficient routine answers and costly ambiguity.
There is no general proof of completeness in this approach. Unknown dependencies and imperfect document inventories remain limits. But making those limits visible changes the role of compression. It becomes an adjustable representation of evidence, with a route back to the underlying records, rather than an irreversible choice about what the answer is allowed to consider.
Information only. No investment, legal, tax, or financial advice.