Is the control group in an AI pilot really untouched by AI?
When agents change colleagues’ work, comparing licensed users with non-users can miss the organization’s actual gain.
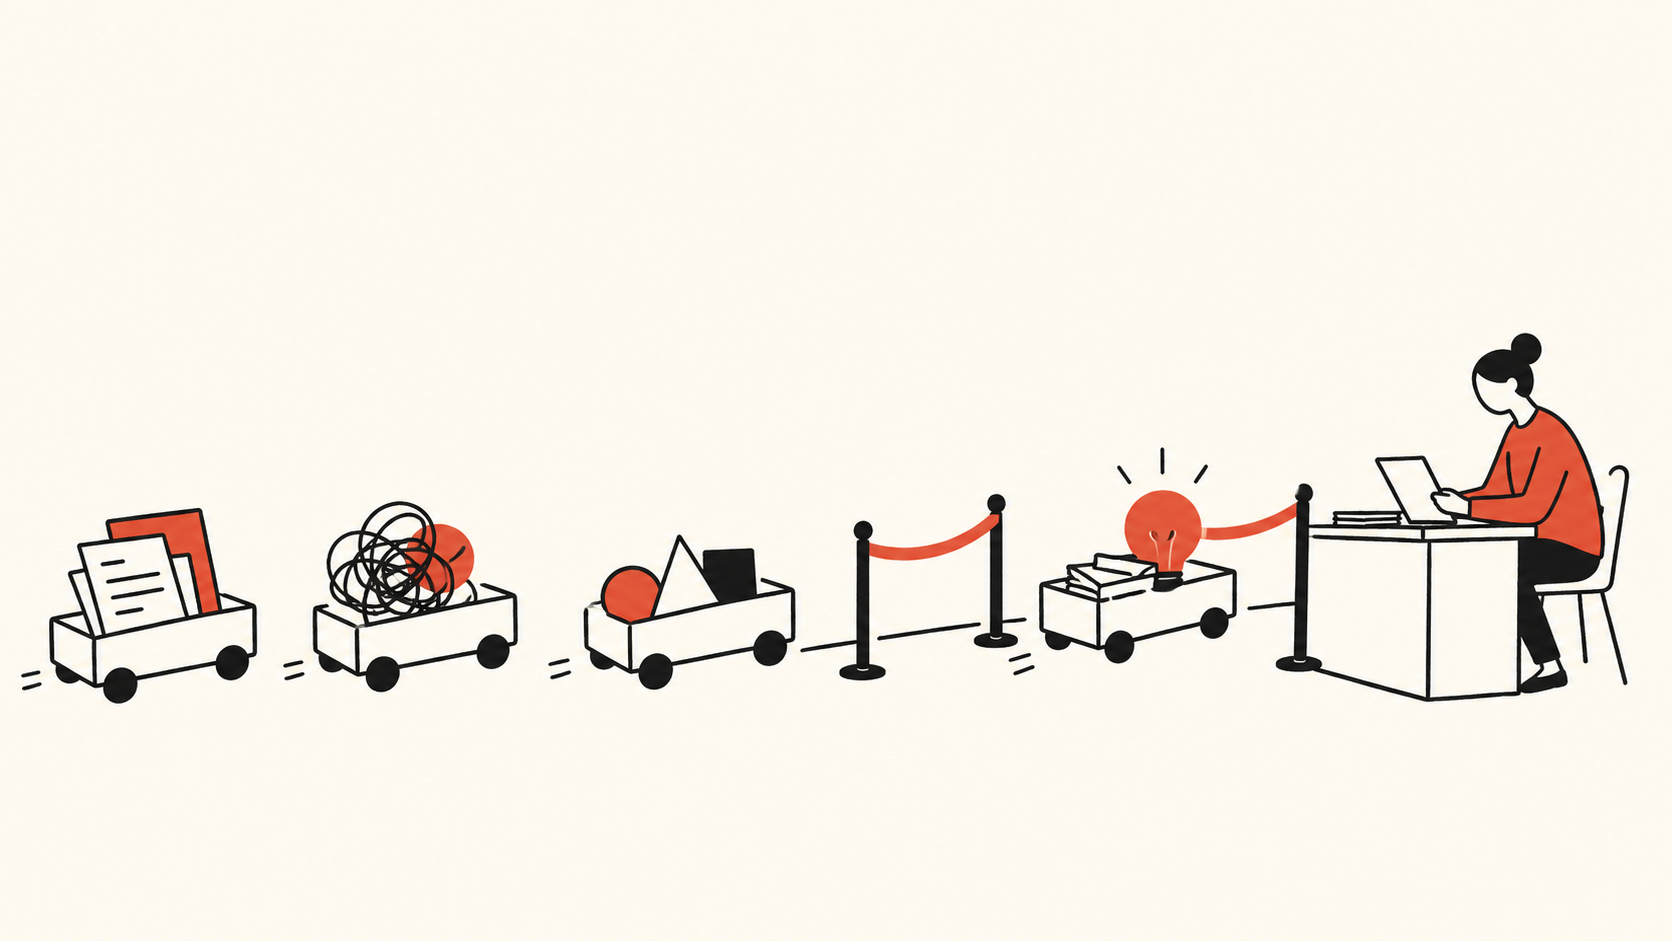
An employee without an AI license can still work in a workplace changed by AI. A colleague may pass on a better-prepared file, request more approvals or leave additional material to check. For a company evaluating an agent pilot, the difference between users and non-users therefore needs careful interpretation. Access to the tool and exposure to its effects are not the same boundary.
Microsoft Research and CMU’s workshop is scheduled for October 22–23, 2026; public synthesis reports are planned afterward. This is a discussion of evaluation, not an issued standard. The practical question considered here is how a buyer can distinguish an improvement for license holders from an improvement for the organization paying for them.
Start with whose work changed
Consider a hypothetical supplier-onboarding team. Some employees receive an agent that organizes documents and prepares review packets. Other employees keep their existing tools. Both send their packets to the same specialists. The company compares the two groups’ preparation times and finds that agent users submit sooner. That would be useful information about a stage of work, but would not establish the effect on approved supplier records.
There are at least two plausible routes beyond that stage. More consistent packets might save the specialists time, benefiting cases from both groups. Alternatively, faster preparation might generate more requests for clarification and leave specialists with additional work. Neither route can be assumed in advance. In this example, people who never opened the agent are part of the mechanism by which its value is realized or dissipated.
J-PAL’s data-analysis guide explains that spillovers arise when people not receiving an intervention are nevertheless affected, potentially biasing estimated effects. The workplace example above is our application of that methodological concern, not a result reported by J-PAL or a named AI vendor.
A deployment ledger should therefore distinguish an account holder, a recipient of AI-assisted work and the owner of a final business outcome. These roles can belong to different people. Treating the purchase list as the complete map of affected employees risks overlooking precisely the work that determines whether preparation savings become useful capacity.
A smaller gap can mean more than one thing
Suppose, within the hypothetical example, specialists use the clearer packets to improve a common template. Non-users now prepare better packets too. The observed user–non-user gap may narrow even though useful knowledge has spread. It would be premature to describe that pattern as proof the agent has little value. Conversely, a large gap could partly reflect a pilot that gives its participants unusual support, while others continue handling the difficult remainder.
These are competing explanations, not diagnoses. The evaluation should collect enough operational context to tell them apart: which templates changed, who received coaching, which cases moved between people and whether review duties were reassigned. Without that record, a precise number can answer a different question from the one management thinks it asked.
The same caution applies to enthusiastic volunteers. Their experience may reveal what motivated employees can achieve with support. It does not automatically reveal what happens when access becomes routine for the whole department. Willingness to participate, actual use and exposure to colleagues’ output should be described separately rather than compressed into a single adoption rate.
Choose the comparison around the decision
J-PAL’s randomization resource notes that group-level assignment can address within-group spillovers, while, all else equal, requiring larger samples for comparable statistical power. It is a design trade-off, not an automatic cure.
For our hypothetical buyer, that suggests first drawing the real work map. If separate operating units have their own reviewers, a unit-level pilot may be more informative for a unit-wide purchase than a seat-by-seat comparison. If every unit depends on one central team, the organizational chart does not create independent boundaries. Simply relabeling departments as experimental groups would leave the shared exposure in place.
The purchasing decision also determines what counts as the intervention. If rollout includes new templates, training and a changed approval process, the business may reasonably want to know whether that package works. The result should then be described as a package effect, not attributed entirely to the model. A separate question about the incremental contribution of the agent requires a comparison that can actually separate those changes.
This is not a ready-made statistical protocol. An organization with few independent units may be unable to obtain a precise causal estimate. A limited operational pilot can still expose workload transfers and implementation failures. Its report should say what it observed and what remains unidentified, rather than inventing certainty from a large number of records handled by a small number of closely connected teams.
Count outcomes without erasing the people between them
Princeton’s SAgE trends review, consulted on October 23, distinguishes capability, human-interaction and systemic-impact evaluation. Evidence at one level does not automatically establish results at another.
Our proposed business reading is to maintain two connected views. One follows useful outcomes, such as supplier records accepted under an unchanged quality requirement. The other follows human effort: preparation, clarification, review and correction, including effort outside the licensed group. More accepted records with the same total effort would mean something different from unchanged output achieved by moving work to an uncounted specialist.
Quality must stay visible alongside quantity. If a pilot accepts thinner evidence or postpones checks, higher throughput may reflect the changed acceptance rule. If it improves completeness and reduces later corrections, that benefit may arrive after the initial measurement window. The buyer should decide in advance which later consequences it can observe and state the limits of that window. A short trial cannot settle a claim about long-term reliability.
Nor should every extra minute be treated as waste. A specialist might spend longer because the agent surfaced a genuine problem that previously went unnoticed. The question is whether the additional work serves a valuable purpose, not whether human involvement always decreases. Case review can help explain this distinction where a time total cannot.
Write the purchase claim at the level the evidence supports
A defensible pilot report might conclude that preparation became faster for participants, that reviewers experienced a particular change in workload, and that the effect on final output remains uncertain. That is a more useful basis for a staged decision than collapsing all three into a productivity headline. It identifies what a wider trial needs to resolve.
The buyer should also preserve disagreement between roles. A positive user survey and a strained review team are not mutually exclusive findings; they may describe different parts of the same workflow. Listening only to the licensed group rewards benefits that are easy to display while leaving transferred costs with people who did not choose the tool.
The value of an agent deployment ultimately depends on the work system it changes. The relevant comparison is not merely who has a login. It is what would have happened to the connected employees and business outcomes under a credible alternative arrangement. Establishing that comparison takes more care than counting active seats, but makes the eventual purchasing claim much clearer.
Information only. No investment, legal, tax, or financial advice.